A benchmark is only useful if you can trust it. Here is exactly how PayerLenz builds every reimbursement figure, so you know what you're looking at before you make an admissions decision with it.
Every PayerLenz benchmark is built from actual behavioral health claims that have been submitted and paid: more than 500,000 of them, across 250 payer groups and 20 states. We don't use surveys, self-reported averages, or rates borrowed from unrelated medical specialties.
Claims enter the PayerLenz pool from two sources: Revenue Logic's own client base, and behavioral health facilities that contribute de-identified data in exchange for plan discounts or search credits. If a claim hasn't generated an EOB, it doesn't build our benchmarks.
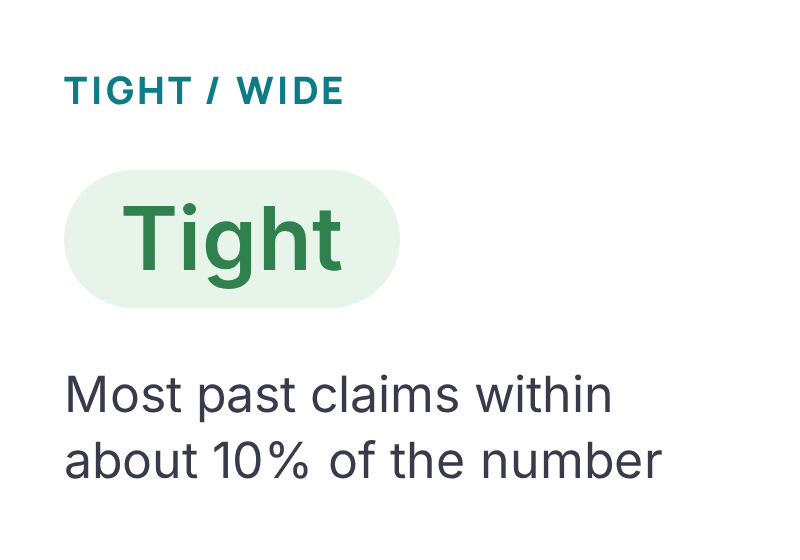
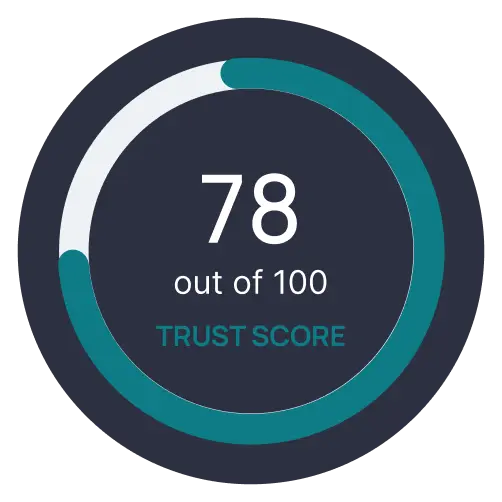
Every figure reads as Tight or Wide. Tight means most past claims came in close to it. Wide means they were spread out, so the figure reads as a midpoint and the range is shown. The 0-100 trust score sits in the detailed view, one click away, and is built from two inputs. The first is claim volume: how many adjudicated claims support this specific payer, state, level-of-care, and methodology combination, log-scaled so depth counts without one giant combination dominating. The second is recency: the share of those supporting claims from the last 12 months. A figure built mostly on recent claims scores higher than one built on old ones, and the score shows it.
A low trust score isn't a hidden flaw. It's a clear signal, telling you to treat that specific figure as directional and verify with a live eligibility check or VOB before relying on it.
Blue Cross Blue Shield is not a single payer. It's a federation of independently operating plans, and reimbursement varies enormously by home plan and alpha prefix.
PayerLenz resolves every BCBS claim to its specific home plan and alpha prefix before it enters a benchmark, and a BCBS benchmark search requires the prefix, so the results reflect the plan that will actually adjudicate the claim, not a blended average across plans that share nothing but a logo.
Out-of-network payment isn't one formula. PayerLenz classifies claims by the pricing methodology the payer applied, and keeps each methodology's rates separate in every result.
Usual and customary
Medicare-multiple non-network reimbursement
Maximum reimbursable charge schedules
Network access pricing
Blending a Medicare-multiple plan with a usual-and-customary plan produces a number that doesn't match any real claim, so we don't.
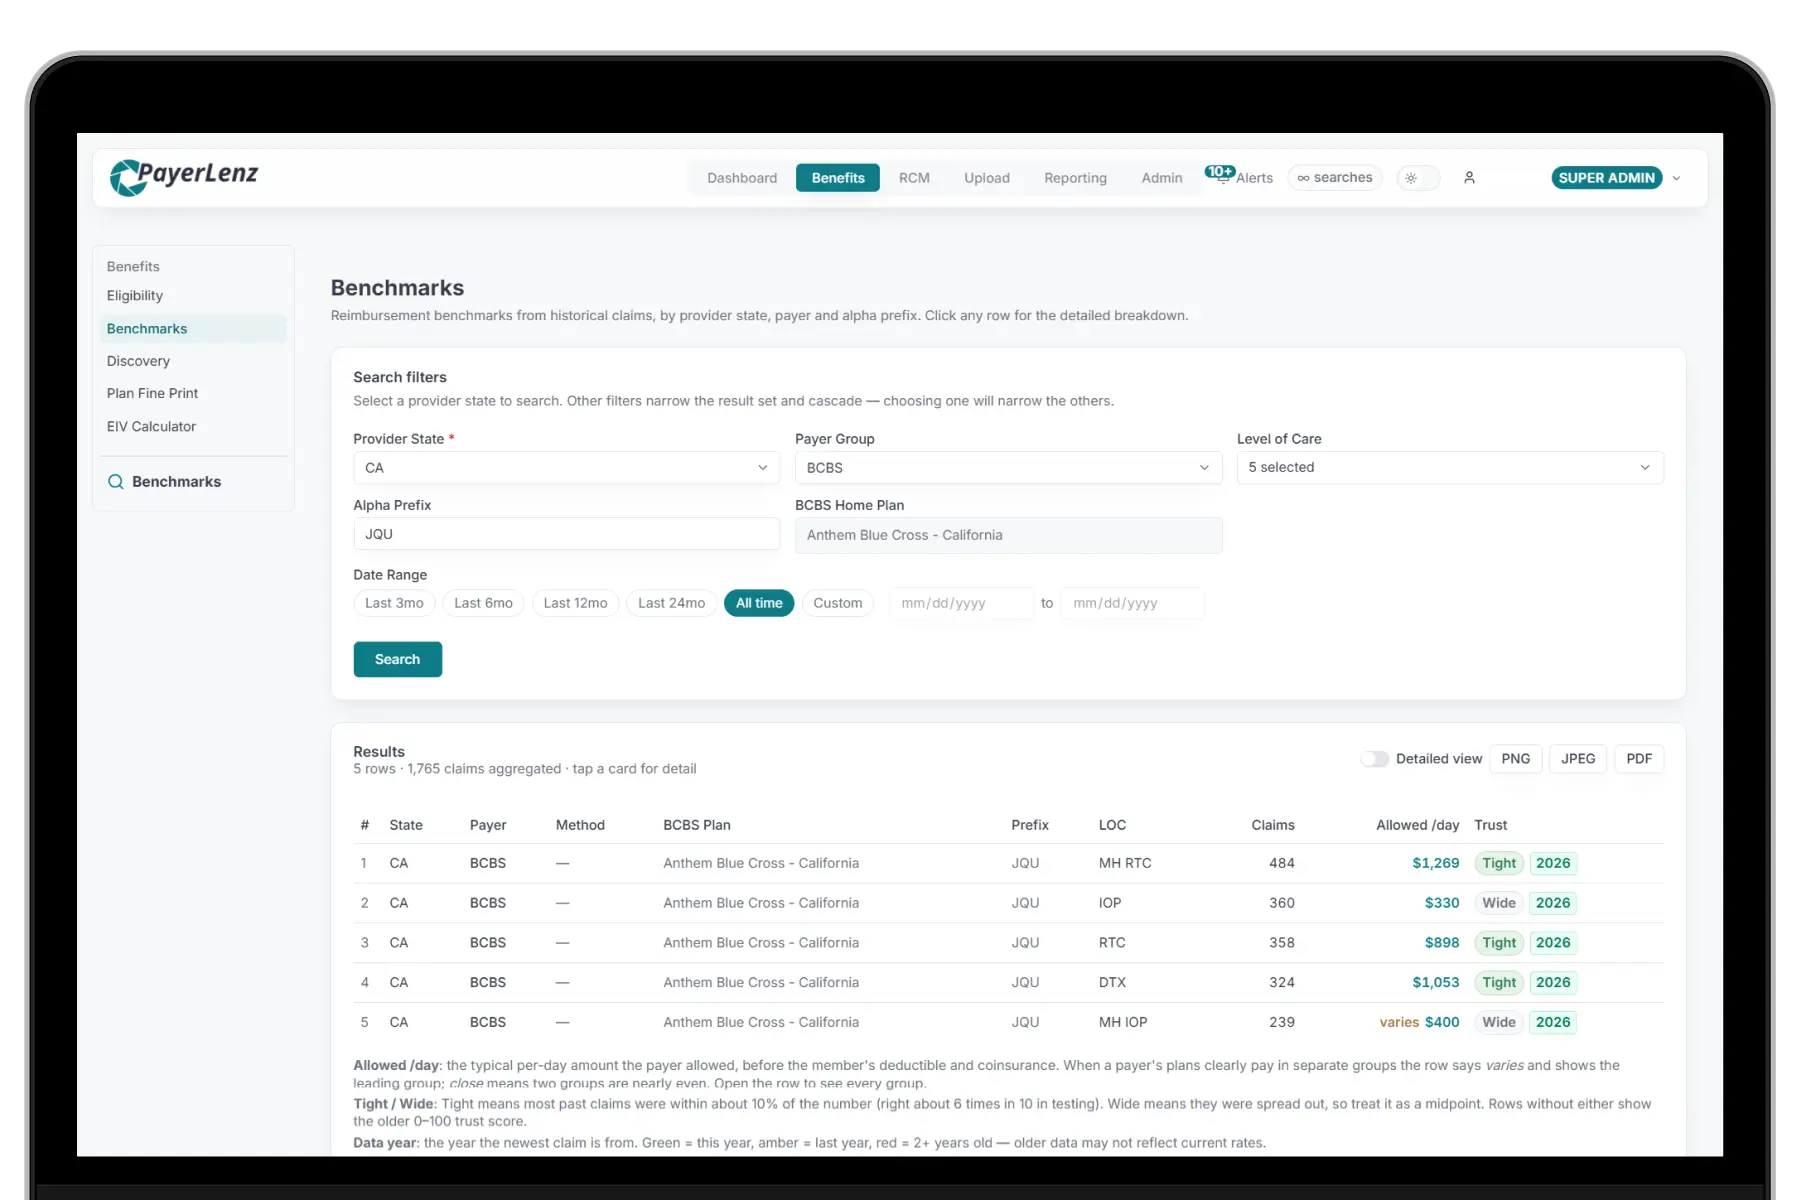
See it for a real payer, state, and level of care with the trust score attached.
You see more than a single number, and the full P25 to P90 spread is one click away. The typical rate leans on recent claims. When a payer's plans pay in clearly separate groups, it's the strongest group, and every group is shown with its share of claims. Reimbursement for the same payer varies by plan design and methodology, and a single average hides that variance, so we show it instead.
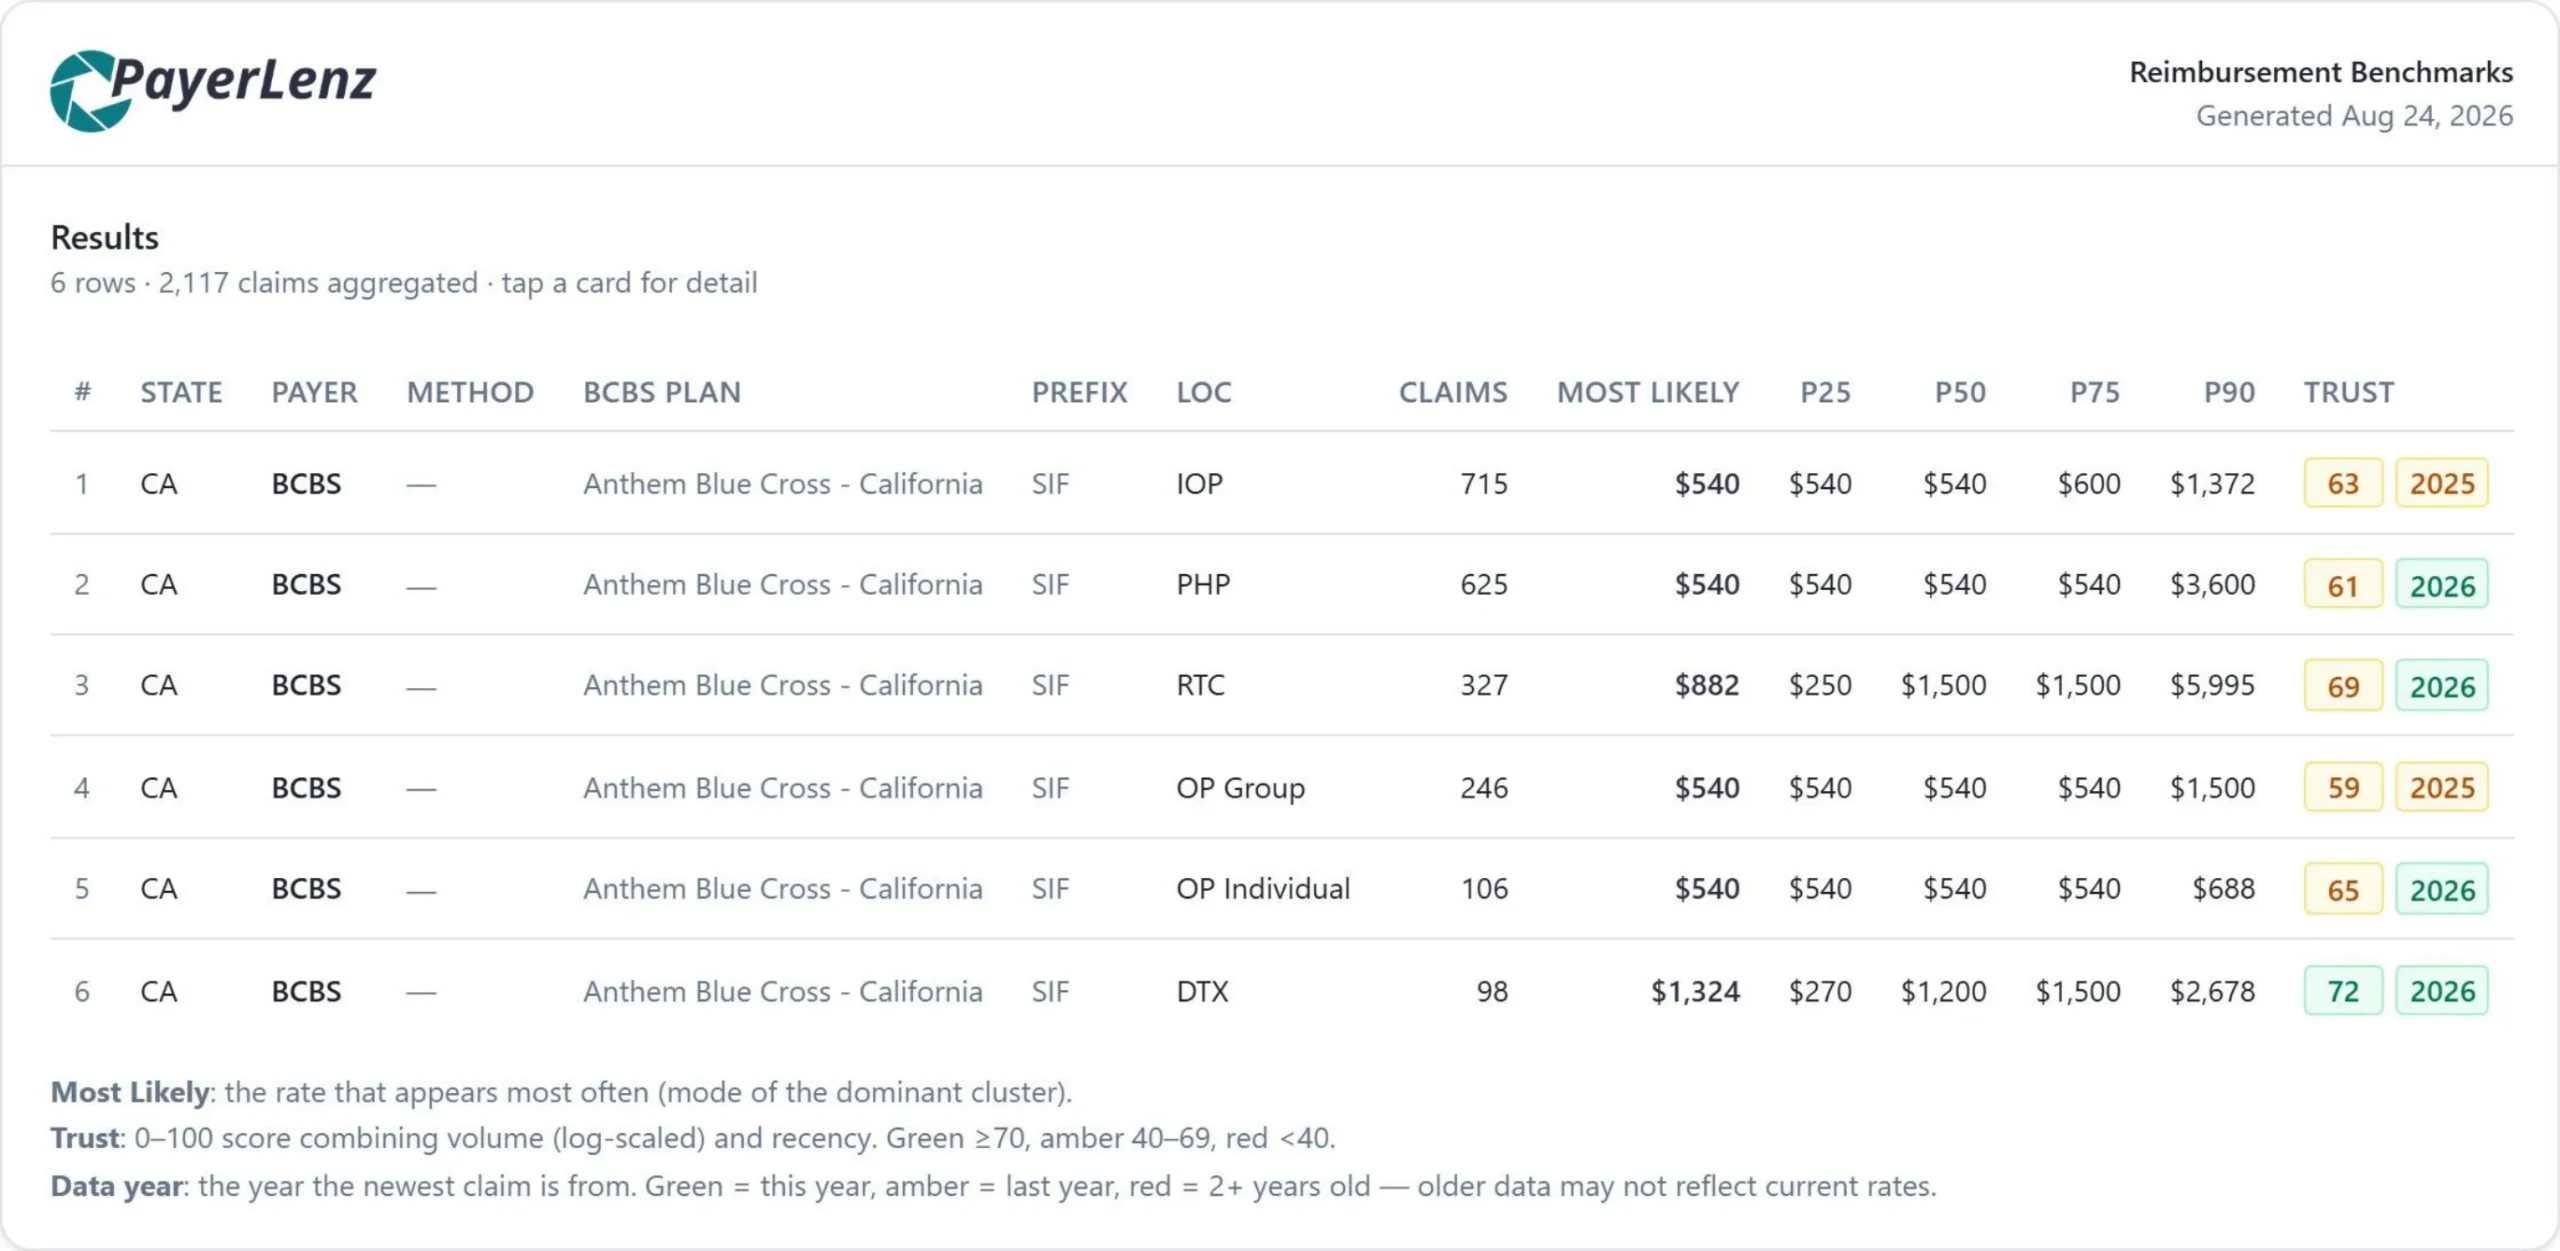
The same methodology this page describes, in a real export.
Everything on this page — the percentile spread, the trust score, the BCBS resolution — shows up in the actual product. This is a real Reimbursement Benchmark export, not a mockup.
The PayerLenz benchmark pool grows as facilities contribute de-identified, adjudicated claims data, and as Revenue Logic's own claim flow continues. More claims mean sharper, more current benchmarks across every payer, state, and level of care. That's why contributing data earns you up to a 25% discount: it makes the tool better for everyone.
See how contribution pricing works